

Redaction: masking rather than replacing
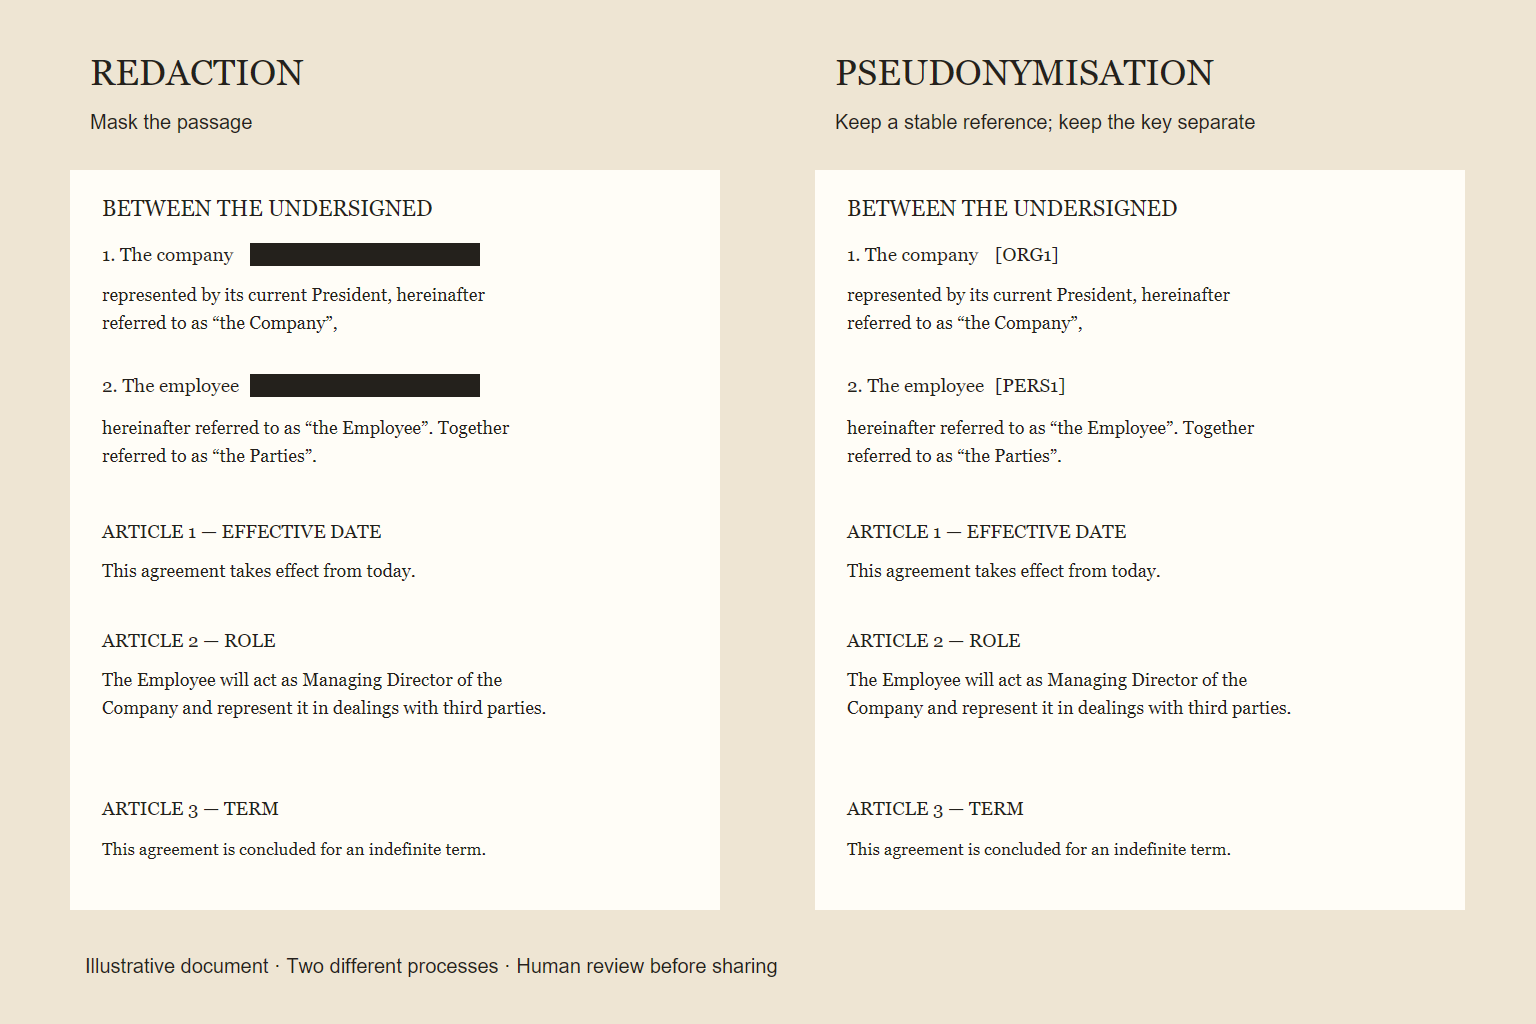
In law firm practice, redaction means masking a passage in a document: a black rectangle, a strike-through or a covered area. The aim is to prevent the recipient from reading what was written there.
The French terms “caviardage” and “caviardisation” describe this same operation. Both refer to masking, rather than replacement with a code.
This has a clear purpose: a scanned signature, a stamp, a header or a passage removed from a document before disclosure. Redaction treats an area. It does not maintain an inventory of entities across the entire matter.
Three limitations follow from this definition.
Redaction is local to an area on the page. It treats what the reviewer has seen or the tool has outlined. Name variants, an email address at the foot of the page and metadata remain outside its scope unless someone addresses them.
Redaction does not produce a mapping table. There is no [PERS1] to refer to later and no key to keep separately. What is masked is hidden from the recipient. Everything else remains readable.
Redaction is not a GDPR category. The regulation addresses anonymisation and pseudonymisation. The effect of masking must then be assessed: does the remaining text still identify a person?
A document management system organises and shares files. It does not redact them. Confusing document management with redaction leads to buying storage software while believing that identifiers have been masked.
Pseudonymisation: replacement with a separate key
Pseudonymisation replaces an identifier with a code. “Dupont” becomes [PERS1]. “SAS Acme” becomes [ORG1]. The same person or company receives the same code on every page and, where possible, across all documents in the matter.
A mapping table makes the process reversible. As long as that table exists, the data remains personal. Whoever holds the key can reverse the operation. This is not anonymisation.
Recital 26 of Regulation (EU) 2016/679 is clear: pseudonymised data that can be attributed to a person using additional information remains information about an identifiable person. Anonymity applies only to information that no longer relates to an identified or identifiable person.
The everyday word “anonymise” remains acceptable on one condition: immediately explain that the operation is reversible, the key is kept separately and the data remains personal.
Two qualities matter. Replacement must be complete for the selected identifiers. It must also be consistent : the same entity receives the same code.
The intelligent pseudonymisation offered by Lexanon follows this approach when selected during analysis: local detection, configurable categories, manual corrections and export with a mapping table.
The differences, point by point
This is where firms most often misunderstand the distinction. A PDF covered with black rectangles is described as “anonymised”. An export using [PERS1] is described as simple redaction. The two operations are not interchangeable.
| Criterion | Redaction (masking) | Pseudonymisation |
|---|---|---|
| Operation | Masks an area (rectangle, strike-through) | Replaces an identifier with a code |
| Visible result | Unreadable passage | [PERS1], [ORG1], stable codes |
| Consistency across the matter | Depends on each area treated | Same entity, same code |
| Mapping table | No | Yes, with a separate key |
| Reversibility | No, for the recipient | Yes, for the key holder |
| Usual data status | Often still personal if context remains | Personal data (reversible) |
| Typical use | Signature, stamp, isolated passage | Document batches, AI, structured sharing |
Redaction removes readability. Pseudonymisation removes an identifier and replaces it with a reference. An AI model can work with [PERS1] and [ORG1]. It cannot work with a page where names are black patches without losing track of the matter.
Conversely, replacing a name with a code does not mask a handwritten signature or a logo. Redaction remains useful for images. Pseudonymisation remains useful for text.
Neither is anonymisation under the GDPR. A PDF where names become [PERS1] and [PERS2], but the chronology, amounts, dispute and key remain, is still a personal data file. So is a PDF where “Dupont” is blacked out on page 3 but readable on page 40.
When to redact and when to pseudonymise
The choice depends on the destination, not on an “anonymise” button.
Redaction is sufficient when the material to remove is isolated and visual: a signature to hide before sending, a stamp or a single paragraph. Two pages, a human recipient and a visual check.
Pseudonymisation is the right tool when identifiers recur, a batch contains dozens of documents or an AI model still needs to understand who does what. The code preserves the structure. The key stays with the firm.
Choose the mode during analysis. The same engine can redact or pseudonymise. The two modes are not run simultaneously. A matter intended for AI needs codes. A document sent to a person may only need masking.
Before sharing with another person—a fellow lawyer, expert, client within a limited scope or service provider—professional secrecy applies alongside the GDPR. In its 17 March 2026 announcement on the guide “Ethics and Artificial Intelligence”, the French National Bar Council (CNB) highlights professional secrecy, the GDPR, competence, caution and independence.
Uploading a named PDF to a web-based AI chat means disclosing the matter to a third party. Redaction must therefore do more than change its appearance. If text remains extractable, the model can still read the names. Pseudonymisation prepares text the model can read without seeing the identity. The legal professional then reads the decoded response on their computer.
Our frequently asked questions about pseudonymisation explain this distinction. As long as a key exists, the data remains personal.
PDF redaction: what the rectangle misses
PDF redaction is the most commonly searched form. Most legal documents still arrive as PDFs, scans or exports. The familiar instinct is to draw a black rectangle, save and send.
This can leave three common leaks, even when a firm believes it has “anonymised” the document.
Text remains beneath the mask. A rectangle drawn as an annotation or layer does not always erase the content. The recipient can select, copy or extract the text. Nothing has actually been removed; only the display has changed.
The identifier appears again later. An 80-page file repeats names, email addresses, phone numbers and sometimes internal references. Manual redaction treats what the reviewer has seen. It can miss a variant, header, note, stamp or scanned signature.
Metadata remains. Author, title, file path, comments: a PDF often carries information outside its main text. An export that ignores these fields leaves a route to re-identification.
Thorough PDF redaction therefore requires these steps, in order:
- Inventory the areas and identifiers to remove.
- Treat extractable text, not just the image.
- Review headers, footers, tables, stamps and signatures.
- Check metadata before export.
- Decide whether text pseudonymisation is more suitable than masking alone.
For a scan, local OCR can precede analysis. Without a text layer, the engine sees only an image. Lexanon's local PDF tools prepare the file through merging and OCR before analysis. Redaction or pseudonymisation is then selected during analysis through Banco.
What the CNIL and EDPB say in 2026
The GDPR does not define “redaction”. Its effect is assessed using the concepts of anonymisation and pseudonymisation, as explained by the CNIL and the European Data Protection Board (EDPB).
On its “Anonymisation of personal data” page dated 19 May 2020, the CNIL explains that anonymisation makes identification practically impossible by any means, irreversibly. It distinguishes this from pseudonymisation using aliases or sequential numbers, which is reversible: the data remains personal.
The CNIL identifies three criteria: singling out, linkability and inference. A CV database in which a name becomes a number unique to that individual is, in its example, pseudonymised rather than anonymised.
On 7 July 2026, the EDPB adopted Guidelines 02/2026 on Anonymisation (version 1.0, with consultation open until 30 October 2026). The CNIL published an overview on 9 July 2026. The EDPB clarifies the concept of anonymous data, taking account in particular of the Court of Justice judgment of 4 September 2025 in Case C-413/23 P. Data is anonymous if it does not relate to an identified or identifiable natural person. This assessment may vary between entities.
The EDPB framework follows the three criteria in Opinion 05/2014: no singling out of records, no linkability and no inference. It proposes two approaches: a contextual assessment based on the recipient's capabilities, and a more cautious simplified approach.
Neither redacting a name nor replacing it with [PERS1] takes a file outside the GDPR when context, amounts or a key remain. A PDF where names become [PERS1] and [PERS2]but the chronology, amounts, dispute and key remain does not meet these criteria. Recital 28 confirms that pseudonymisation can reduce risks; it does not eliminate them.
How Lexanon offers both
Lexanon is desktop software. Analysis runs on your computer. No document is sent away for processing.
During analysis, Lexanon offers both options using the same engine: Banco. The firm chooses either redaction or pseudonymisation.
Redaction. Banco detects identifiers and masks them. The recipient can no longer read the passage. There is no [PERS1] code to refer to or table to take away. Useful when removing an identifier without leaving a reference.
Pseudonymisation. Banco detects the same categories, then replaces them. Each person becomes [PERS1]. Each organisation becomes [ORG1]. The same entity receives the same code within the document and, if the batch is analysed together, across the other documents in the matter. A mapping table stays with the customer in a .lexanon-keyfile. The data remains personal. The operation is reversible for the key holder.
The firm imports a file or folder (PDF, DOCX, PPTX, CSV, XLSX, images, TXT, EML, MSG), chooses the categories, then selects the mode. Analysis runs locally.
Before export, the legal professional reviews the results: approving or disabling an entity and adding or removing an occurrence. This review does not replace the choice of processing mode.
For AI queries, pseudonymisation is the useful mode: the model—Claude, ChatGPT, Mistral or Gemini, depending on the firm's key—sees codes rather than names. This is BYOK: the API key belongs to the customer and is stored locally. Lexanon decodes the response on the computer. The legal professional reviews it with the original names restored.
Two limitations remain. Lexanon does not guarantee exhaustive detection or the compliance of a disclosure. The legal professional decides whether to share.
A 7-day trial lets you test this workflow. A guided demonstration is available here. The Lexanon plans explain the trial and subscription.
FAQ
What is the difference between redaction and pseudonymisation?
Redaction masks an area with a rectangle, strike-through or blackout. Pseudonymisation replaces an identifier with a stable code and keeps a separate mapping table. A blacked-out name is not [PERS1]. The former removes readability; the latter preserves a useful reference for a case or an AI model. Neither amounts to GDPR anonymisation if context or a key remains.
Is redacting a PDF enough before sharing a document?
Effective PDF redaction starts with an inventory, including headers, notes and metadata. A black rectangle is not enough if the text remains selectable or the same identifier appears elsewhere. For batches or AI use, text pseudonymisation is often more appropriate. The legal professional remains responsible for the final review.
Does automatic redaction replace manual review?
No. Redaction or pseudonymisation software speeds up detection and applies more consistent processing. It guarantees neither completeness nor compliance. Automation can miss edge cases, images or identifying context. The legal professional's review still determines whether a document can leave the firm.
Are redaction and GDPR anonymisation the same thing?
No. Redaction removes visible identifiers. Under the GDPR, anonymisation aims to make identification practically and irreversibly impossible. If a mapping table exists, or context still allows someone to be identified, the data remains personal. In litigation files, the operation is usually pseudonymisation, or sometimes simply masking.
Does Lexanon offer redaction or pseudonymisation?
Both are available at the analysis stage through the Banco engine. Redaction masks identifiers. Pseudonymisation turns them into consistent codes, with the key kept by the customer. Choose the mode according to the destination. In pseudonymisation mode, the data remains personal as long as a key exists.
Conclusion
The redaction sought by law firms is not document management or pseudonymisation: it is masking. Pseudonymisation replaces identifiers with codes and keeps the key separate. Masking may suffice before sharing with a person. For AI or batches, codes maintain consistency. During analysis, Lexanon offers both options through Banco, followed by review. As soon as a key exists, the data remains personal and the GDPR continues to apply.
Sources
- Regulation (EU) 2016/679, Recitals 26 and 28 (EUR-Lex)
- CNIL, Anonymisation of personal data, 19 May 2020
- CNIL, overview of the EDPB guidelines, 9 July 2026
- EDPB, Guidelines 02/2026 on Anonymisation, 7 July 2026 (PDF)
- EDPB, press release of 8 July 2026
- CNB, adoption of the guide on ethics and AI, 17 March 2026
Article by Arthur Groleau. Published on 27 August 2026. Last updated on 27 August 2026.
Notice. This article provides general information about redaction and pseudonymisation of legal documents. It is not personalised legal advice. The firm remains responsible for assessing each document and deciding whether to disclose it.